dsh-project-memory
If this plugin saves you an hour of debugging, a star would be appreciated.




A persistent project development memory for DeepSeek Harness (dsh) agents. Built specifically for project development, natively integrated with dsh's task system: task lists and files read during a session are automatically persisted as cross-session task records, with tasks ↔ files linked — workflows can be switched and resumed, no need to re-scope the whole project, solving context loss. Underneath sits a hybrid index: document chunks, code symbols, experience notes and insights each form a layer, scored per layer and merged into one ranking. Documents (PDF/Markdown/txt) and code symbols are stored separately per workspace; documents are automatically cross-linked to the code symbols they mention. Experience notes (problem → solution) are automatically deduplicated, preventing repeated mistakes. Data survives session compaction and handover; recalls include path:line citations for source verification.
The plugin keeps a compact project memory on disk, with every entry pointing to a concrete file and line — the agent can reorient quickly instead of re-reading the whole project.
Features
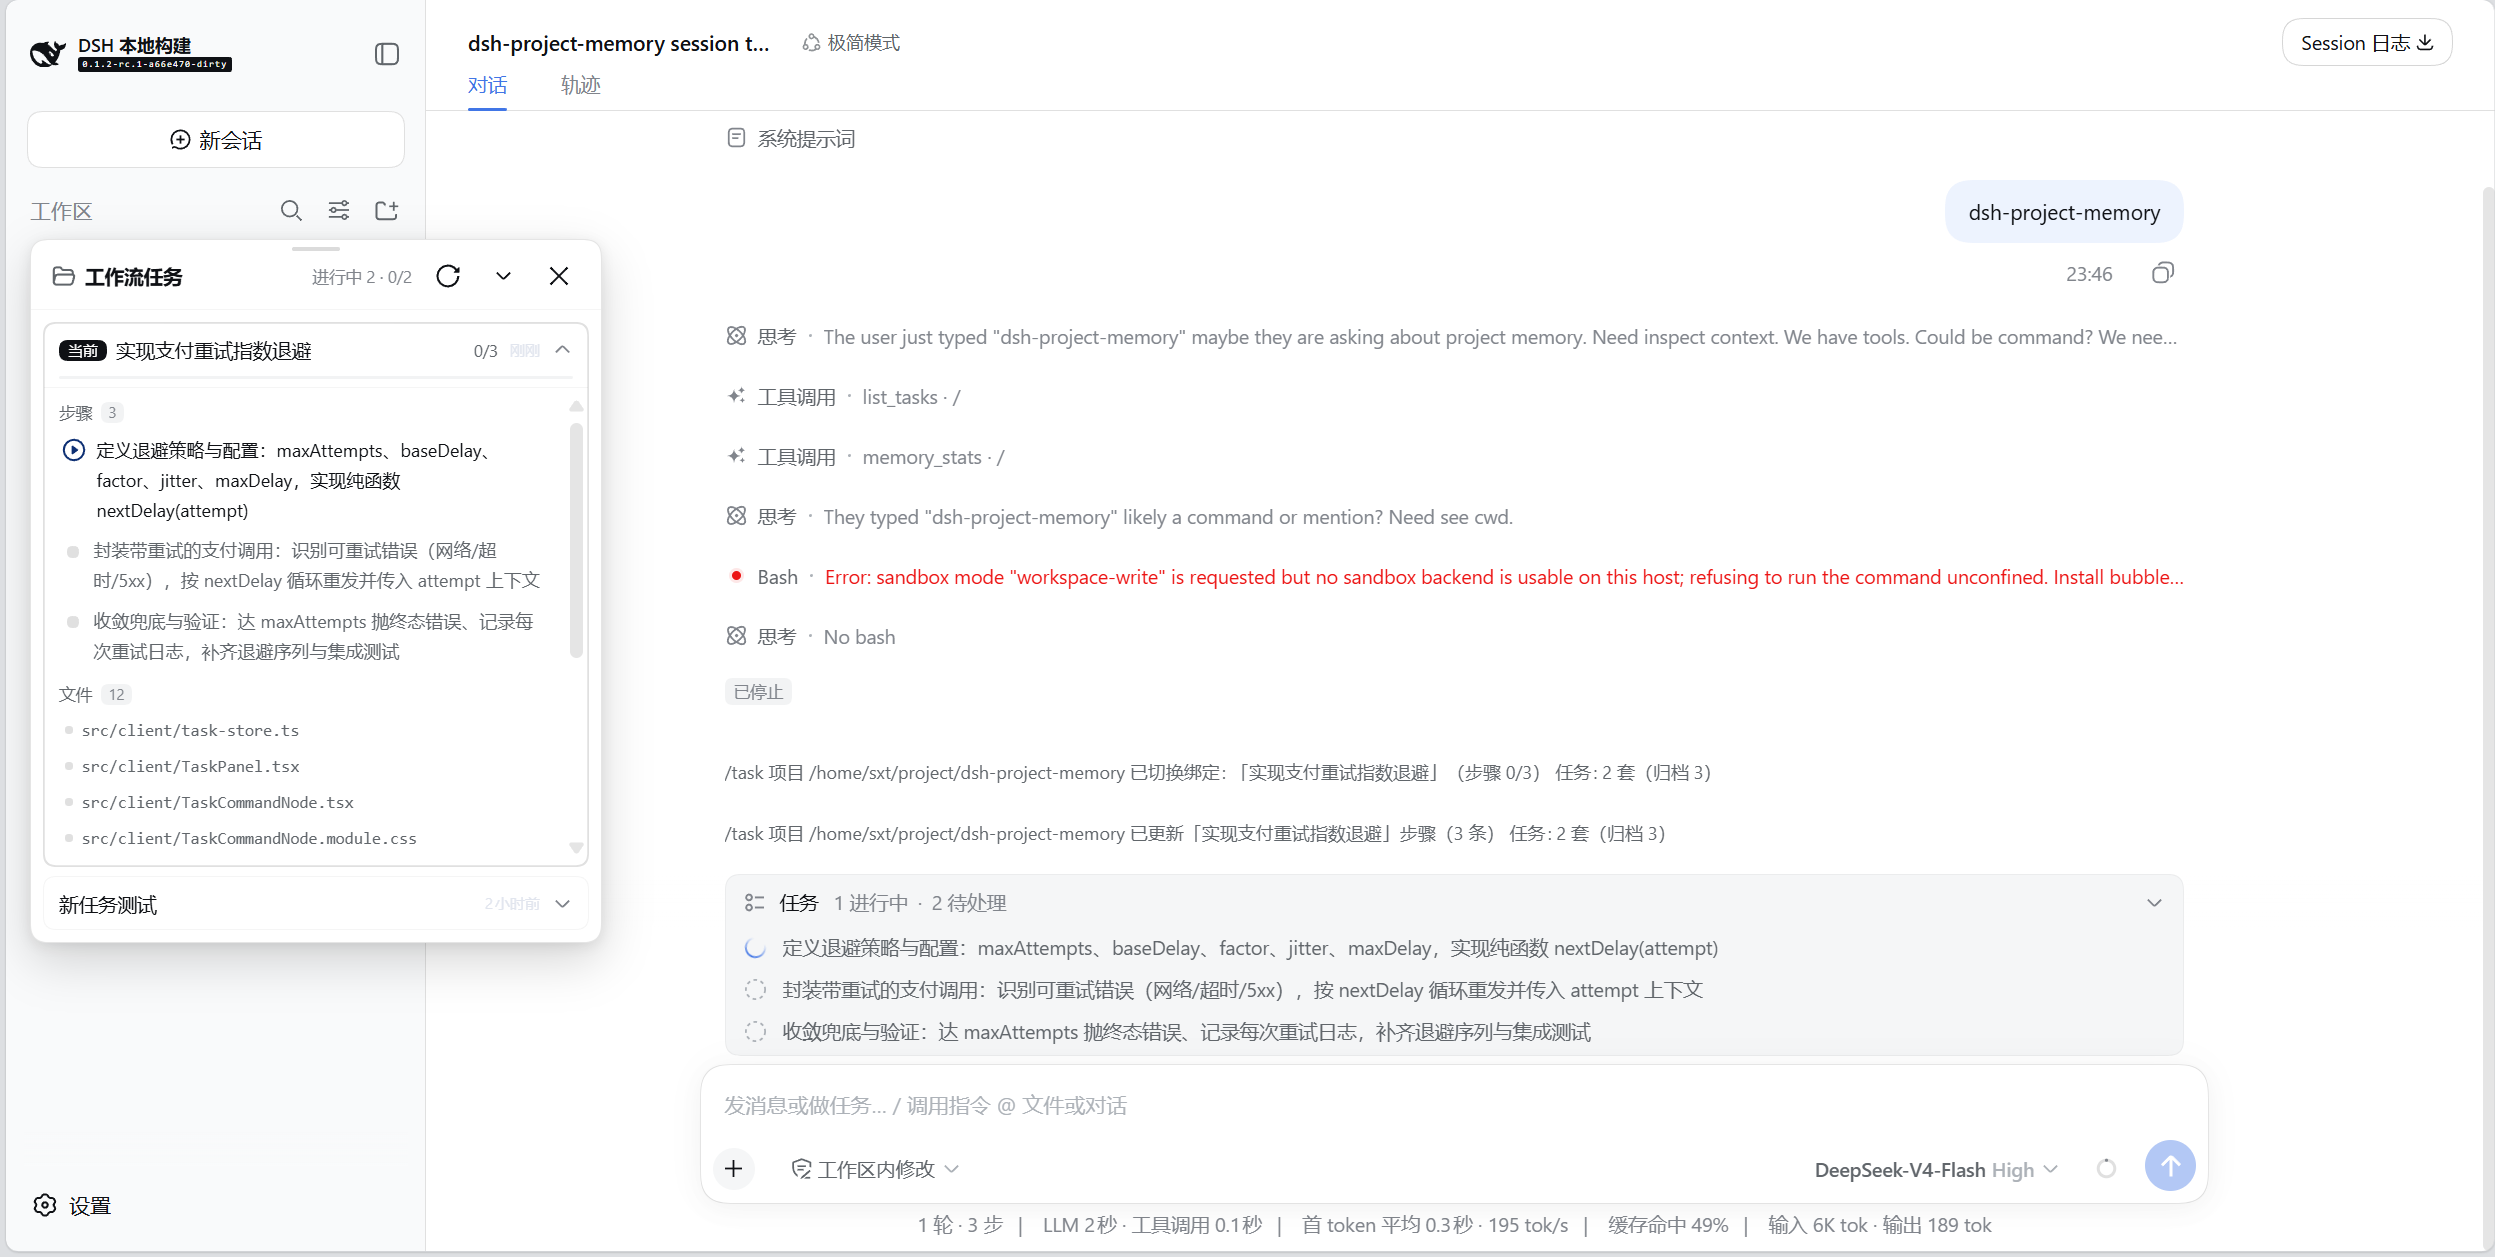
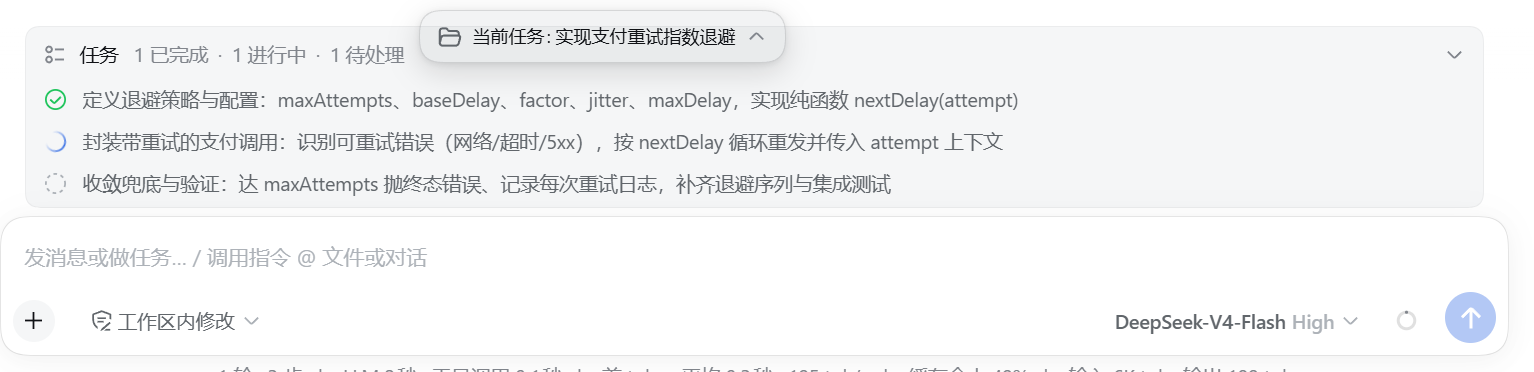
- TaskBridge: cross-session development tasks — the session's todo list and the files it touches are persisted as per-project task entities, so a workflow can be switched and resumed without re-scoping the project. Associated files stay in recency-weighted order (a read never outranks a written file), so a resumed session sees where to look first. New sessions continue with
list_tasks→select_task. Work delegated to subagents creates no task. On hosts without session events the task tools still work as a plain record list. - Task panel and editing — draggable cards show a task's steps and files, and can collapse to a mini-bar or be hidden. Title, steps and status can be edited inline, writing back through the same path as model updates; four visual themes change material, geometry, typeface and density only, and colours follow the host. The panel stays hidden until summoned, syncs in the background on session switch, never reopens itself after a refresh, and a render failure cannot take down the host.
- Document memory — PDF, Markdown and plain text are chunked and summarized without a model call. Each entry keeps a short summary for injection, a bounded term set for recall, and a citation back to the source.
- Code symbol memory — a dependency-free scanner extracts functions, classes, methods, interfaces and type aliases with signatures; covered languages are JavaScript/TypeScript, Python, Go, Rust, C/C++/C#, Java and shell. Where
typescriptis installed, an optional second layer adds inferred return types, generics and interface shapes; it runs in the background and never blocks indexing. - Automatic, read-time memorization — with lazy indexing (default), a file is memorized the moment the model reads it, so memory grows as a byproduct of normal work rather than an upfront scan.
index_repoor a watched root can cover the rest of the tree; a background poll only re-indexes files that changed. - Doc ↔ code cross-linking — a document that mentions a symbol is surfaced when that symbol is queried. Links are resolved against the current symbol table, so they cannot go stale.
- Hybrid recall — ranked search over documents, symbols, experience notes and insights, with optional LLM query expansion. The experience/insight layers are re-ordered by cosine when
leanvecis present — installed by default, absent ⇒ pure lexical. Tuned for CJK: phrase boost, a synonym table, and CJK-aware boundaries for doc↔symbol linking. Russian (Cyrillic) is supported too: word splitting, a stopword list and Snowball stemming, so Russian queries hit Russian notes and take part in dedup. - Experience notes — problems → solutions, deduplicated by overlap rather than repeated, bounded by project size, and surfaced both by search and by the same injection path as lessons.
- Tiered insight memory (lessons / decisions / procedures) — one entity across task, project and global scope. Near-duplicates merge or reinforce, and promotion moves an entry between scopes instead of copying it. Use is recorded, so decay and capacity rank by activity rather than age alone. The panel exposes a per-scope view for reviewing and editing entries. That list is ordered newest-first and loaded incrementally: 30 entries at a time, with the next page prefetched before the reader reaches the bottom and off-screen rows skipped by the renderer, so a large memory stays responsive.
- Triggered injection — an insight may carry an authored trigger: only
whentriggers,guardnarrows it, andpreventsrecords what breaks without the entry. Corpus text can never trigger an injection; the statistical channel is gated separately and silent by default. Evidence is graded by source: only host facts (structured tool calls,fs/todoevents) and irreversible actions named by the human (commit / publish / release / push / deploy / go public) can inject full text; prose mentions of delete / clean up / render / benchmark only feed the hint channel, and subagent prompts plus notice-shaped messages never count as actions. - Usage is a skill too — it registers
project-memoryinto the hostskillsregistry (a directory bundle withscripts/pm-digest.mjs,resourceBasepointing inside the package). The model loads the query/write workflow on demand instead of carrying it in every prompt; hosts without askillsservice skip it silently.
Installation
The plugin relies only on stable public APIs declared through peerDependencies.
cd dsh-project-memory && dsh plugin --profile web add . -w
The -w (workspace-root) flag is required: the profile directory is a pnpm workspace root, and pnpm rejects add there without it. From elsewhere, use the same command with an absolute path.
The plugin is also published on npm as a scoped package:
dsh plugin --profile web add @yolk_vat-y/dsh-project-memory -w
Each indexed project has its own store at <root>/.dsh-project-memory/. It keeps itself out of git by default — there is nothing to add to your .gitignore. Global-scope entries are kept outside the project in ~/.config/dsh-project-memory/global.json; point insight.globalFile elsewhere to move it.
Usage
The tools below are invoked by the agent, not typed by the user. In the chat, just ask naturally — e.g. "index this project" or "what does the auth module do?" — or simply keep working, and the agent calls the matching tool automatically. By default files are indexed the moment the model reads them, so memory fills in while you work. watch_repo keeps explicitly-watched roots fresh in the background; index_repo forces a full backfill (unchanged files are skipped).
In a git work tree the corpus is whatever git ls-files --cached --others --exclude-standard lists — tracked files plus untracked files that are not ignored — so .gitignore, nested rules included, decides what gets remembered. A directory that is not a git work tree falls back to a plain walk (no ignore rules). Lazy indexing applies the same check when a file first enters the store; a file that is already indexed is refreshed on later reads without asking git again — if .gitignore starts excluding it, the index_repo / watch_repo scan drops it. An explicit index_doc bypasses .gitignore, but still respects roots.exclude, readability and the size limit, and its entry survives later scan passes for as long as the file exists.
| Tool | Purpose |
|---|---|
index_doc file_path |
Index one document (PDF/MD/txt): chunk, summarize deterministically, and store with a path:line citation. Unchanged files are skipped. |
index_repo root |
Index a whole project: documents get deterministic summaries, code files get a token-free symbol table. Incremental and self-healing: the store follows the file listing, so deleted, ignored or moved files are dropped (an entry created by an explicit index_doc is kept while its file still exists), and documents are cross-linked to symbols. A non-existent or excluded root is rejected before anything is written. |
watch_repo root |
Enable automatic refresh: a background poll detects new and changed files and re-indexes only those. A watched root is recorded in that project's store, so it resumes when dsh starts there; a non-existent or excluded root is refused, roots that disappear are dropped rather than re-created. |
memory_stats root |
Show what the store contains: totals, last index time, and the per-file list sorted by recency. |
query_memory query |
Ranked search over documents, symbols, experience and insights, optionally query-expanded by the LLM. type selects a layer (all / doc / symbol / experience / insight / task). Returns hits with relative scores, sources or insight ids, and doc→symbol references. |
list_tasks |
List task records for the project (archived marked). Call first in a new session before continuing work. |
select_task |
Bind the session to a task so its todo list and file reads sync into it. Exact taskId, or exact title (multiple matches return candidates; no match creates a new task). Pass title with taskId to rename. Auto-unarchives. |
archive_task |
Archive a task (hide from default views, exclude from capacity, stop syncing). select_task restores it. |
show_task_panel |
Show the task panel in the UI. Call when the user asks to see the task list or when you want to display the panel. |
/tasks (typed by the user, not the model) |
The only user command: shows the task stack and drives the workflow card. Every other action is a sub-verb invoked by card buttons: switch / archive / unbind / rename / todos … / step / step-move / step-text for tasks, insight list [scope] [offset] [limit] / confirm / promote / demote / archive / restore / delete / save / edit for memory. |
remember problem solution |
Save an experience note. It is a kind: 'experience' insight — same store, same dedup and same delete path as lessons / decisions / procedures. Similar problems merge or overwrite instead of duplicating. |
forget id_or_query |
Delete memories — lessons / decisions / procedures and experience notes alike, across task / project / global in one call, without knowing which layer the entry lives in. An exact id deletes that one entry; keywords match by query-side coverage (matched query terms ÷ query terms). Real deletion, no undo; when keywords match more than the cap (default 10) it deletes nothing and only lists the candidates. The 5 most recently deleted entries are kept as full entries in that layer's deleted.json next to its store (<root>/.dsh-project-memory/deleted.json for the project layer, beside the global file for global), and the deletion result prints that path — read it and save again to recover a mis-delete. |
save_lesson |
Save a lesson / decision / procedure at task, project or global scope; passing id overwrites that entry in place (only the fields you pass, the previous values stay in prev — write them back with the same id). Before writing it compares against existing memory: cosine ≥ 0.9 auto-overwrites that entry, ≥ 0.7 reports the nearest id in the result; without leanvec it falls back to lexical overlap ≥ 0.7 merge / 0.65–0.7 reinforce. Two tasks hitting the same insight promote it task → project, three or more → global. Key params: id, title, kind, scope, the content (pattern/fix, choice/reason or steps), and trigger (when is the only trigger surface, guard narrows it, prevents records what breaks without it). |
/tasks appears in the web / menu inside an icon-bearing Workflow group, with three view entries — Tasks / Project Memory / Global Memory (labelled in the UI language). It is the plugin's only registered command; every other action rides it as a sub-verb driven by card buttons.
How it works
The design follows four principles:
- Volatility — context is ephemeral; it is lost when a session is compacted.
- Persistence — the memory is stored on disk and survives compaction and new sessions.
- Compactness — one bounded declaration line per symbol, and a ≤300-char summary plus a bounded term set per document chunk. Doc→symbol links are not stored; they are computed at read time.
- Verifiability — recalls carry a
path:linecitation where applicable, so the agent can confirm details against the source.
With default lazy indexing, building the memory does not require an upfront scan: files are memorized as the model reads them, so the memory grows to cover what has been worked with; index_repo or a watched root can cover the rest. Re-reading an unchanged file is a no-op, so the memory stays fresh with minimal ongoing overhead.
Project- and task-scope memory is stored per project and follows the codebase: changed files are re-extracted by content hash, deleted files are removed. Experience notes are ordinary kind: 'experience' entries in insights.json: recallable, deduplicated, and eligible for the same gated hint channel as lessons.
Design
.dsh-project-memory/
  format.json      layout marker (v2, sharded)
  shards/          one self-describing JSON per indexed source file — writes touch only dirty shards
  watch.json       watched roots
  tasks.json       TaskBridge task entities (cross-session)
  binding.json     current session ↔ task binding
  insights.json    project-scope memory (lessons / decisions / procedures / experience notes) — one entity
  vectors.json     optional semantic index (only when the vector layer runs)
  injection-audit.jsonl   one line per real injection (what / why / dropped / budget)
  admission-shadow.jsonl  one line per step, all scored candidates + features (offline replay)
Global-scope entries are not stored under the project: they live in insight.globalFile (default ~/.config/dsh-project-memory/global.json) so every project sees them.
- Incremental — a content hash per file; only changed files are re-extracted.
- Cross-linking — a returned document chunk resolves the symbols it mentions against the current symbol table and appends them as
references, so a doc indexed before its symbols still links correctly. - Query expansion — when enabled,
query_memoryasks the LLM to rewrite the query into several variants (synonyms, EN/CN, identifier guesses) and merges the scores; when off, queries never touch the LLM. Indexing itself is model-free. - Consistency — the fact layer follows the codebase (hash re-extract / remove-on-delete); experience entries are updated through the same supersede and
forgetpaths as other insights. Writes take a cross-process directory lock (.write.lock) around a short read-modify-write, so two dsh instances can share one project store: shards converge byindexedAt, a save that cannot get the lock is retried and flushed again at exit, failures stay silent by default (DSH_PROJECT_MEMORY_DEBUG=1prints one diagnostic line), and entries deleted by another process are not resurrected by a stale in-memory snapshot.
Architecture (Task Panel)
TaskPanel (Container)
├── task-data-store  (server data, cross-tab sync via BroadcastChannel)
├── task-ui-store    (local UI state, localStorage)
├── task-hooks       (useTaskDrag, useTaskEdit)
└── TaskComponents   (MiniBar, TaskCard — presentational only)
The workflow panel is collapsible, adapts to dsh and theme plugin styles, and offers four card styles.
Configuration
| Key | Default | Meaning |
|---|---|---|
memoryDir |
.dsh-project-memory |
store directory inside each indexed root |
chunkChars / maxChunksPerFile |
3000 / 40 | max chars per document chunk, max chunks per document |
maxFileSizeMb |
10 | skip documents (incl. PDF) and code files larger than this (MB); see the per-file memory budget below |
maxPdfPages |
1000 | PDF page cap |
maxOutputChars |
8000 | cap for query_memory result text (chars) |
lazyIndexing |
true | index files the moment the model reads them |
autoIndexOnFirstUse |
false | full scan of the current working directory on plugin load (opt-in) |
watch / watchInterval |
true / 30 | background refresh; base poll interval in seconds (polls stay quiet while a turn is running — a 5-minute fallback keeps external edits fresh — and one merged scan runs at turn end; idle polls back off up to 2 minutes and reset on any change) |
maxScanFiles / maxScanDepth |
20000 / 12 | per-scan caps on files and directory depth; a truncated pass is reported and never removes what it did not reach. Cannot be disabled: 0 or any invalid value falls back to the default |
allowUnsafeRoots |
false | releases the built-in excluded list for every root decision (including lazy indexing, session audit and TaskBridge). It only applies to the built-in list — roots.deny / roots.exclude still win; to release a single directory, prefer an exact roots.allow entry |
roots.allow / roots.deny / roots.exclude |
[] / [] / [] |
custom root lists (machine/profile level, CLI and web alike). allow / deny match the directory itself exactly; exclude is a path-boundary prefix and covers the whole subtree (no file under it enters the index). Priority: exclude > deny > allow > built-in list; the filesystem root can never be a root. ~ / ~/... expansion, non-absolute entries are ignored with a one-time stderr warning, Windows is case-insensitive |
llmQueryExpansion / expansionCount |
false / 6 | expand queries via the LLM before search (off by default to save tokens); max variants |
tsPath / enableTypeScript |
(auto) / true | optional absolute path to a specific typescript install; set enableTypeScript: false to disable the type-aware layer entirely |
tasklist.enabled / tasklist.syncHostOnAdopt |
true / true | TaskBridge auto-sync (task entities from the session todo list and file reads); push a bound task's steps to the host task list so dsh mirrors it |
insight.* |
dedupOverlap 0.7 · reinforceBand 0.65 · autoMergeCos 0.9 · autoMergeMargin 0.05 · hintCos 0.7 · maxForgetMatches 10 · maxProject 100 · maxGlobalProcedures 200 · promoteConfidence 0.7 · globalPromoteTasks 3 · decayDays 90 · globalFile (auto) |
insight dedupe / auto-overwrite / near-neighbour hint / delete cap / reinforce / promotion / capacity / archive settings. autoMergeCos / hintCos = 0 turns that band off |
reflection.enabled |
false | LLM reflection, draft-only at task level (fires on task switch-away / archive). cooldownMs 1800000, maxLessonsPerReflect 3, maxDecisionsPerReflect 2 |
autoContext.enabled |
true | silent injection wrapper (resident task card + gated items); inert until the host exposes a resolvable session cwd. maxTokens 400 (per step), editedMax 3 (recently written files shown on the task card), signalMinRatio 0.5 (a hint must reach half of its layer's top score), skipEchoSelfTodo true, budgetLog off, reinjectItemsAfter 0 (steps before the same insight may be injected again), rootNotice true |
autoContext.gateCooldownSteps |
2 | minimum number of pre-steps between two item injections (the resident task card is exempt — it is a state snapshot). This is the main "don't inject often" dial |
autoContext.maxItemsPerSession / autoContext.maxItemCharsPerSession |
60 / 24000 | runaway fuse, not a throttle — a hard per-session ceiling by count and characters; once reached, the item channel stays silent for the rest of the session |
autoContext.hintMinCoverage |
0.45 | absolute floor for the statistical channel: the IDF-weighted share of the query's information mass the entry covers. A ratio-only threshold cannot tell signal from "best of a bad lot" |
autoContext.hintMinMatched / autoContext.hintMinSupport |
2 / 0.15 | a hint must share at least this many terms with the query, and at least this share of the query's terms must exist in the corpus at all — otherwise the channel stays silent this round |
autoContext.vectorDir |
unset | optional semantic layer over the experience/insight layers, on by default via the leanvec optionalDependency (≈85 MB table, ≈+45 MB RSS). off forces pure lexical; a path or DSH_LEANVEC_DIR overrides it. Re-orders only, returned counts unchanged; while it is active only entries that got no cosine are still filtered by lexical match count |
autoContext.vectorAlpha |
0.5 | weight of (1-α)·lexical + α·cosine in those layers; 0 disables re-ranking only (write-side dedup stays on), 1 (pure vector) measured worse |
autoContext.vectorDedup |
true | write-side near-duplicate detection (cosine ≥ 0.9 auto-overwrite, ≥ 0.7 near-neighbour hint). Independent of vectorAlpha; false keeps recall ranking untouched |
autoContext.vectorItemMin / autoContext.vectorSpeakMin |
unset | experimental absolute-cosine gates for the hint channel (per-entry floor / channel-level semantic rescue). Uncalibrated — unset means off; see the evidence in src/auto-inject.js before enabling |
autoContext.auditLog |
true | append one JSONL line per actual injection to injection-audit.jsonl (what / why / dropped / budget); rotates to .1 past auditMaxBytes (262144). Silent on I/O errors |
autoContext.shadowLog / autoContext.shadowMaxBytes |
true / 524288 | append one JSONL line per step (including steps that injected nothing) to admission-shadow.jsonl: scored candidates with their features and the gate that rejected each one — what makes a threshold change answerable offline. Disk only, never in the prompt; rotates keeping one .1 generation |
Toggling features
The two most relevant switches are lazyIndexing (index a file the moment the model reads it; default on) and autoIndexOnFirstUse (full scan of the current working directory on plugin load; default off). Lazily indexed project roots are automatically registered with the watcher, so changed files stay fresh without an explicit watch_repo.
Root resolution. In order: an explicit root argument; a registered root (watch_repo); the nearest ancestor with a VCS marker (.git/.hg/.svn) or a build/manifest marker (package.json, go.mod, Cargo.toml, pyproject.toml, …); the session working directory, unless it is on the excluded list. A file that matches none of these is not indexed.
When the root comes from the working directory, the model gets one notice per session naming it and how to change it; mute with autoContext.rootNotice: false. Starting dsh in a container directory such as ~/workspace therefore makes that directory the root, and memory spans everything beneath it up to the scan limit — start dsh inside the project for one store per project.
Excluded directories. By default, these are not used as a root, matched exactly (subdirectories are unaffected): the filesystem root, the home directory, temp directories — os.tmpdir() and the shared ones (/tmp, /var/tmp, %TEMP%, %SystemRoot%\Temp) — and system / package-manager prefixes (/opt/homebrew on POSIX; %SystemRoot%, %ProgramFiles%, %ProgramData% on Windows). A session in one of these runs without memory, with one line on stderr.
Custom root lists. The roots block overrides that decision. All three accept ~ / ~/...; non-absolute entries are ignored with a one-time stderr warning (relative paths would resolve against the host cwd and are unpredictable); Windows is case-insensitive:
roots.allow— allow a directory even when it is on the built-in list, matched exactly. The filesystem root is not eligible.roots.deny— this directory cannot be a root, matched exactly; its subdirectories can still be roots of their own.roots.exclude— no file in this subtree enters the index, matched by path-boundary prefix (subdirectories included); no new root is inferred inside it either. A complete scan of a parent root skips it and removes entries already indexed under it.
deny only decides whether the directory itself can be a root: when a parent is already a root, files under a denied child are still indexed by that parent — use exclude (or .gitignore, which the git-aware scan already honours) to drop the files too. Explicit index_doc also respects exclude and returns Not indexed for a file under it.
Priority is exclude > deny > allow > built-in list. allowUnsafeRoots: true only releases the built-in list; deny / exclude still win. The same verdict is shared by explicit tool calls, lazy indexing, watch, the session audit trail and TaskBridge. Roots refused by the current policy are dropped from watch.json on startup. Configure under config: of - id: project-memory (CLI and web alike); the web UI has no dedicated settings page, so edit the profile.
Scan limits. One pass covers at most maxScanFiles files (20000) and maxScanDepth directory levels (12). A truncated pass is reported in the index_repo result and logged once per root by the watcher, and it does not remove entries it did not reach. A directory that cannot be read (e.g. EACCES) counts as a truncated pass too and is named in the result: a read failure is not a deletion.
Per-file memory budget. maxFileSizeMb is a memory gate, not a disk-space preference. Indexing a file first materializes it — the whole buffer plus decoded text for code, or every PDF page's text plus the joined markdown for documents — and the peak scales with the file's size. Measured on this machine with npm run bench:peak (peak RSS fitted against disk size over a 1–50 MB ladder, one fresh process per point): ≈10× for typical source code (1 declaration per ~1.4 KB), ≈22× for symbol-dense code (1 per 220 B) and ≈20× for a text-heavy PDF, on top of a ~52 MB process baseline plus a one-off ≈175 MB the first time a PDF is parsed. The 10 MB default therefore keeps a single file at roughly +300 MB RSS for code and +370 MB for a PDF; raising the cap raises that ceiling proportionally.
The store lives in the tree it indexes and ignores itself: a * rule inside the store keeps it out of git status and git add -A, and means git clean -fd leaves it alone. To commit project memory deliberately, git add -f .dsh-project-memory — tracked files are not affected by ignore rules.
Settings live in the plugin's config object. To change them, add an override entry to your profile's cordis.patch.yml — for the web profile that is ~/.dsh/profiles/web/cordis.patch.yml:
- id: project-memory
  config:
    lazyIndexing: true          # on: index files as the model reads them (default)
    autoIndexOnFirstUse: false  # off: no upfront full scan (default)
    llmQueryExpansion: false    # off: do not spend tokens on LLM query expansion (default)
    watch: true                 # on: background refresh for watched roots (default)
    watchInterval: 30           # base poll interval; quiet during a turn, one merged scan at turn end, idle backoff to 2 min
    maxScanFiles: 20000         # per-scan file cap (truncation is reported, never deletes)
    maxScanDepth: 12            # per-scan directory-depth cap
    enableTypeScript: true      # on: type-aware enhancement when TS is installed (default)
    # allowUnsafeRoots: false   # release the built-in list; prefer roots.allow below
    # roots:                     # custom root lists (empty by default)
    #   allow: [/srv/projects/demo]        # exact release of a built-in directory (filesystem root excluded)
    #   deny: [/srv/shared]                # exact: this directory cannot be a root; children still can
    #   exclude: [/srv/monorepo/archive]   # subtree prefix: no file under it enters the index
    # tsPath: /custom/path/to/typescript  # optional: force specific TS install
    # autoContext:              # note: the next two keys live under autoContext, not at the top level
    #   budgetLog: once         # debugging: log budget drops to stderr (default off = silent)
    #   reinjectItemsAfter: 20  # debugging: allow the same insight again after N steps (default 0 = once per session)
Only list the keys you want to change; the rest fall back to the plugin defaults. Verify the result with dsh --profile web --dump-config.
For a one-off run without editing the profile, pass the override as a CLI patch overlay:
dsh web --patch ./config.yml
where config.yml contains the same override block.
Performance
Measured on real projects (2026-10-13)
Four corpora, one Linux machine (Node 24.19), each run twice with the second, warm-cache run quoted. "Cold index" is a full index pass (walk + hash + extract + commit); "query" runs the shipped scorer over 100 sampled queries; "re-index 1 file" is the watch re-index core (read + extract + commit), which excludes the lazy path's root-resolution / .gitignore overhead.
| Corpus | Files / entries | Cold index | Cold load | Query p50 / p95 | Re-index 1 file | Store content / on disk | Heap after load |
|---|---|---|---|---|---|---|---|
| Frontend app (code only) | 289 / 2,142 | 246 ms | 8 ms | 0.76 / 1.4 ms | 0.3 ms | 0.66 MB / 1.52 MB | 6.3 MB |
| Docs workspace (Markdown + PDFs) | 249 / 977 | 705 ms | 10 ms | 1.8 / 5.5 ms | 0.4 ms | 1.31 MB / 1.84 MB | 6.8 MB |
| TypeScript monorepo, 3,000-file slice | 3,000 / 17,576 | 1.9 s | 70 ms | 9.2 / 18.9 ms | 1.9 ms | 10.9 MB / 18.9 MB | 22.7 MB |
| TypeScript monorepo, whole tree | 12,634 / 80,231 | 7.8 s | 278 ms | 40.6 / 74.8 ms | 7.2 ms | 42.0 MB / 75.7 MB | 75.2 MB |
How it scales. Re-indexing a changed file costs O(file), not O(corpus) — 0.3–7.2 ms across every corpus above. Cold load (≈22 µs/file), query (≈0.5 µs/entry on the largest corpus) and resident heap (≈1.5 KB/entry once queried) grow linearly with the index, which keeps small and mid-size projects in the single-digit-millisecond range. Re-reading a file that is already indexed costs ≈0.01 ms: it stops after one stat plus a cached record lookup, with no read, no hash and no git check-ignore.
read+hashdepends on the OS page cache — 2.3 s cold vs 0.27 s warm on the 12,634-file tree — so the table quotes the warm figure.
Synthetic Benchmark (Node 24.19, Linux)
| Scenario | Scale | Measured |
|---|---|---|
| Full cold index | 5,000 files / 20k entries | 284 ms avg (p50 286) |
| Cold load | 5,000 files | 58 ms |
| Hot lazy re-index (single file) | 5k files | p50 2.5 ms / max 6.7 ms |
| query_memory (cached) | 5k files / 20k entries | p50 2.9 ms / p95 6.0 ms |
| query_memory (cached) | 1k files / 4k entries | p50 0.5 ms / p95 1.1 ms |
| Full cold index | 10,000 files / 40k entries | 558 ms avg (p50 540) |
| Cold load | 10,000 files | 117 ms |
| Hot lazy re-index (single file) | 10k files | p50 5.5 ms / max 8.4 ms |
Generated code (~4–5 symbols/file), measured 2026-10-13. Reproduce with
npm run bench:synthetic -- 5000(scripts/bench-synthetic.mjs). Pure indexing overhead, no LLM calls. The first query after a write rebuilds the IDF cache (141 ms at 40k entries, 68 ms at 20k, 17 ms at 4k); later queries hit it.
Reproduce it on your own project
The measurement ships with the repository and with the published npm package (scripts/ is part of the tarball). It needs no dsh instance, no network and no model calls, and never touches your project's own store — results go to a temp directory and are removed afterwards:
npm run bench -- /path/to/your/project
# or, with options:
node scripts/bench.mjs /path/to/your/project [--json] [--samples 100] [--no-pdf] [--keep]
It reports the cold index split into read+hash / extract / commit, cold load, IDF rebuild, cold and hot query latency (p50/p95/max over 100 sampled queries through the shipped scorer), single-file hot re-index, store size, resident heap and bytes per entry. Example — the frontend app row above:
cold index   246 ms   (read+hash 8 ms · extract 222 ms · commit 14 ms)   ← 2nd, warm-cache run
store        0.66 MB content · 1.52 MB on disk · 325 bytes/entry · cold load 8 ms
memory       heap 6.3 MB after load → 6.9 MB after the first query (RSS 62 MB)
hot query    p50 0.76 ms · p95 1.4 ms          (2,142 entries)
re-index 1 file  p50 0.3 ms
Pass --queries your-queries.json to run the labeled-set method (hit@5 / hit@10 / MRR) against your own project.
Design tradeoffs
- A short filesystem lock, not an embedded database — each save holds an exclusive
.write.lockonly for the read-modify-write (parsing stays outside it) and waits synchronously for up to 15 s for a busy peer (correctness comes from acquiring the lock, not from background retries); a write that still cannot land is registered for a synchronous flush when the process exits or the plugin is disposed, without interrupting the user — memory writes are idempotent and cheap to redo; setDSH_PROJECT_MEMORY_DEBUG=1for a one-line diagnostic. The lock carriespid/host/token: a live same-host holder is never preempted, release verifies ownership, and a crashed same-host lock is reclaimed immediately. Two dsh instances can share one store. No WAL, no daemon, no native dependency. - Watch: compute outside, commit inside — no lock is held during parsing, and polling with mtime + content hash is used instead of
fs.watch: it behaves identically on network drives, Docker volumes and WSL, without duplicate-trigger or missed-event failure modes. - Corrupt shards are quarantined, not repaired — a shard that fails to parse is renamed and only that file is re-indexed, so there is no WAL or embedded database adding native dependencies, lock contention and failure modes of their own.
- Vectors re-rank, they do not rank — on a paraphrased-query set, pure vector replacement is worse than BM25 (hit@10 53% vs 69%) while weighted fusion helps at small k (hit@3 53% vs 50%), so the optional layer only re-orders the experience/insight layers and never gates. Lexical retrieval still answers the queries this plugin targets: on a real project with 29 labelled queries, file-level hit@5 is 96.6%, and whole-chunk terms raise document term coverage from 27.3% to 100% with MRR unchanged (0.958 vs 0.955).
- Indexing is deterministic and model-free — a model at index time would make two indexings of one document differ, and a wrong translation at query time means zero recall; rules plus symbol links cover the common cases and work offline.
- Model-facing memory: the agent writes, no human in the loop — the consumer is the agent, usually headless, so memory that only promotes when someone clicks a card would never promote at all.
draftis a provenance marker plus an evidence threshold, not an approval queue. - Full entries returned directly — entries are already compact, so returning them whole is more verifiable and one round-trip cheaper.
forgetby query is aggressive; use IDs for precision — experience notes are low-risk and high-volume, so stale noise hurts more than an over-broad delete. For exact deletion use the ID shown byquery_memory.- TypeScript enhancement is optional and lazy — it runs in the background, never blocks indexing, and falls back to the regex scanner; its queue is bounded and deduplicated by content, and any dropped files are reported. The default lib is not loaded: inference that depends on global types (
Promise/Array/DOM) degrades toany/unknown, while explicit annotations are unaffected.
Development (for contributors)
These commands are for maintaining the plugin code — regular users do not need them. Installing the plugin only requires the command in Installation.
npm install
npm test                    # 892 tests
npm run eval:injection      # synthetic pool P/R: precision 0.93 / recall 1.00, + a 3-scenario hint-only group
npm run eval:injection -- --store .dsh-project-memory/insights.json   # replay on YOUR store; control group is a hard gate
npm run selfcheck:triggers  # which entries can still push, which declarations are dead (reads your local store)
npm run bench -- /path/to/project   # index/query performance on any project — no dsh needed
npm run bench:peak          # peak-RSS budget of maxFileSizeMb, measured on a 1–50 MB ladder
npm run schema:size         # per-tool fixed prompt cost: chars and a same-scale token estimate
Release notes live in CHANGELOG.md and on GitHub Releases.
License
MIT — see LICENSE.
Copyright (c) 2026 00080000 <3388065969@qq.com>